Kimi K3.1 Pro lands fourth on the Artificial Analysis index, ahead of GPT-6 Astra and Fable 5.1
Moonshot's new open-weight model scores 65.7% on Terminal-Bench 4.0, 0.7 points behind Claude Opus 5.5. The company says full weights arrive by November 4.
Kimi K3.1 Pro has a 1-million-token context window and a Highspeed variant that runs 2-3 times faster. On Artificial Analysis's index it scores 55, fourth overall, while using 150M tokens against a median of 87M.
Moonshot also says it deliberately kept the open weights below its own pipeline's offensive-cyber capability.

What Moonshot shipped
Kimi K3.1 Pro is a post-trained version of K3, which the company calls a "3T-class open-weight model," with a 1-million-token context window. The Highspeed variant runs 2-3 times faster. Full weights are due by November 4, 2026; API pricing is on a separate page.
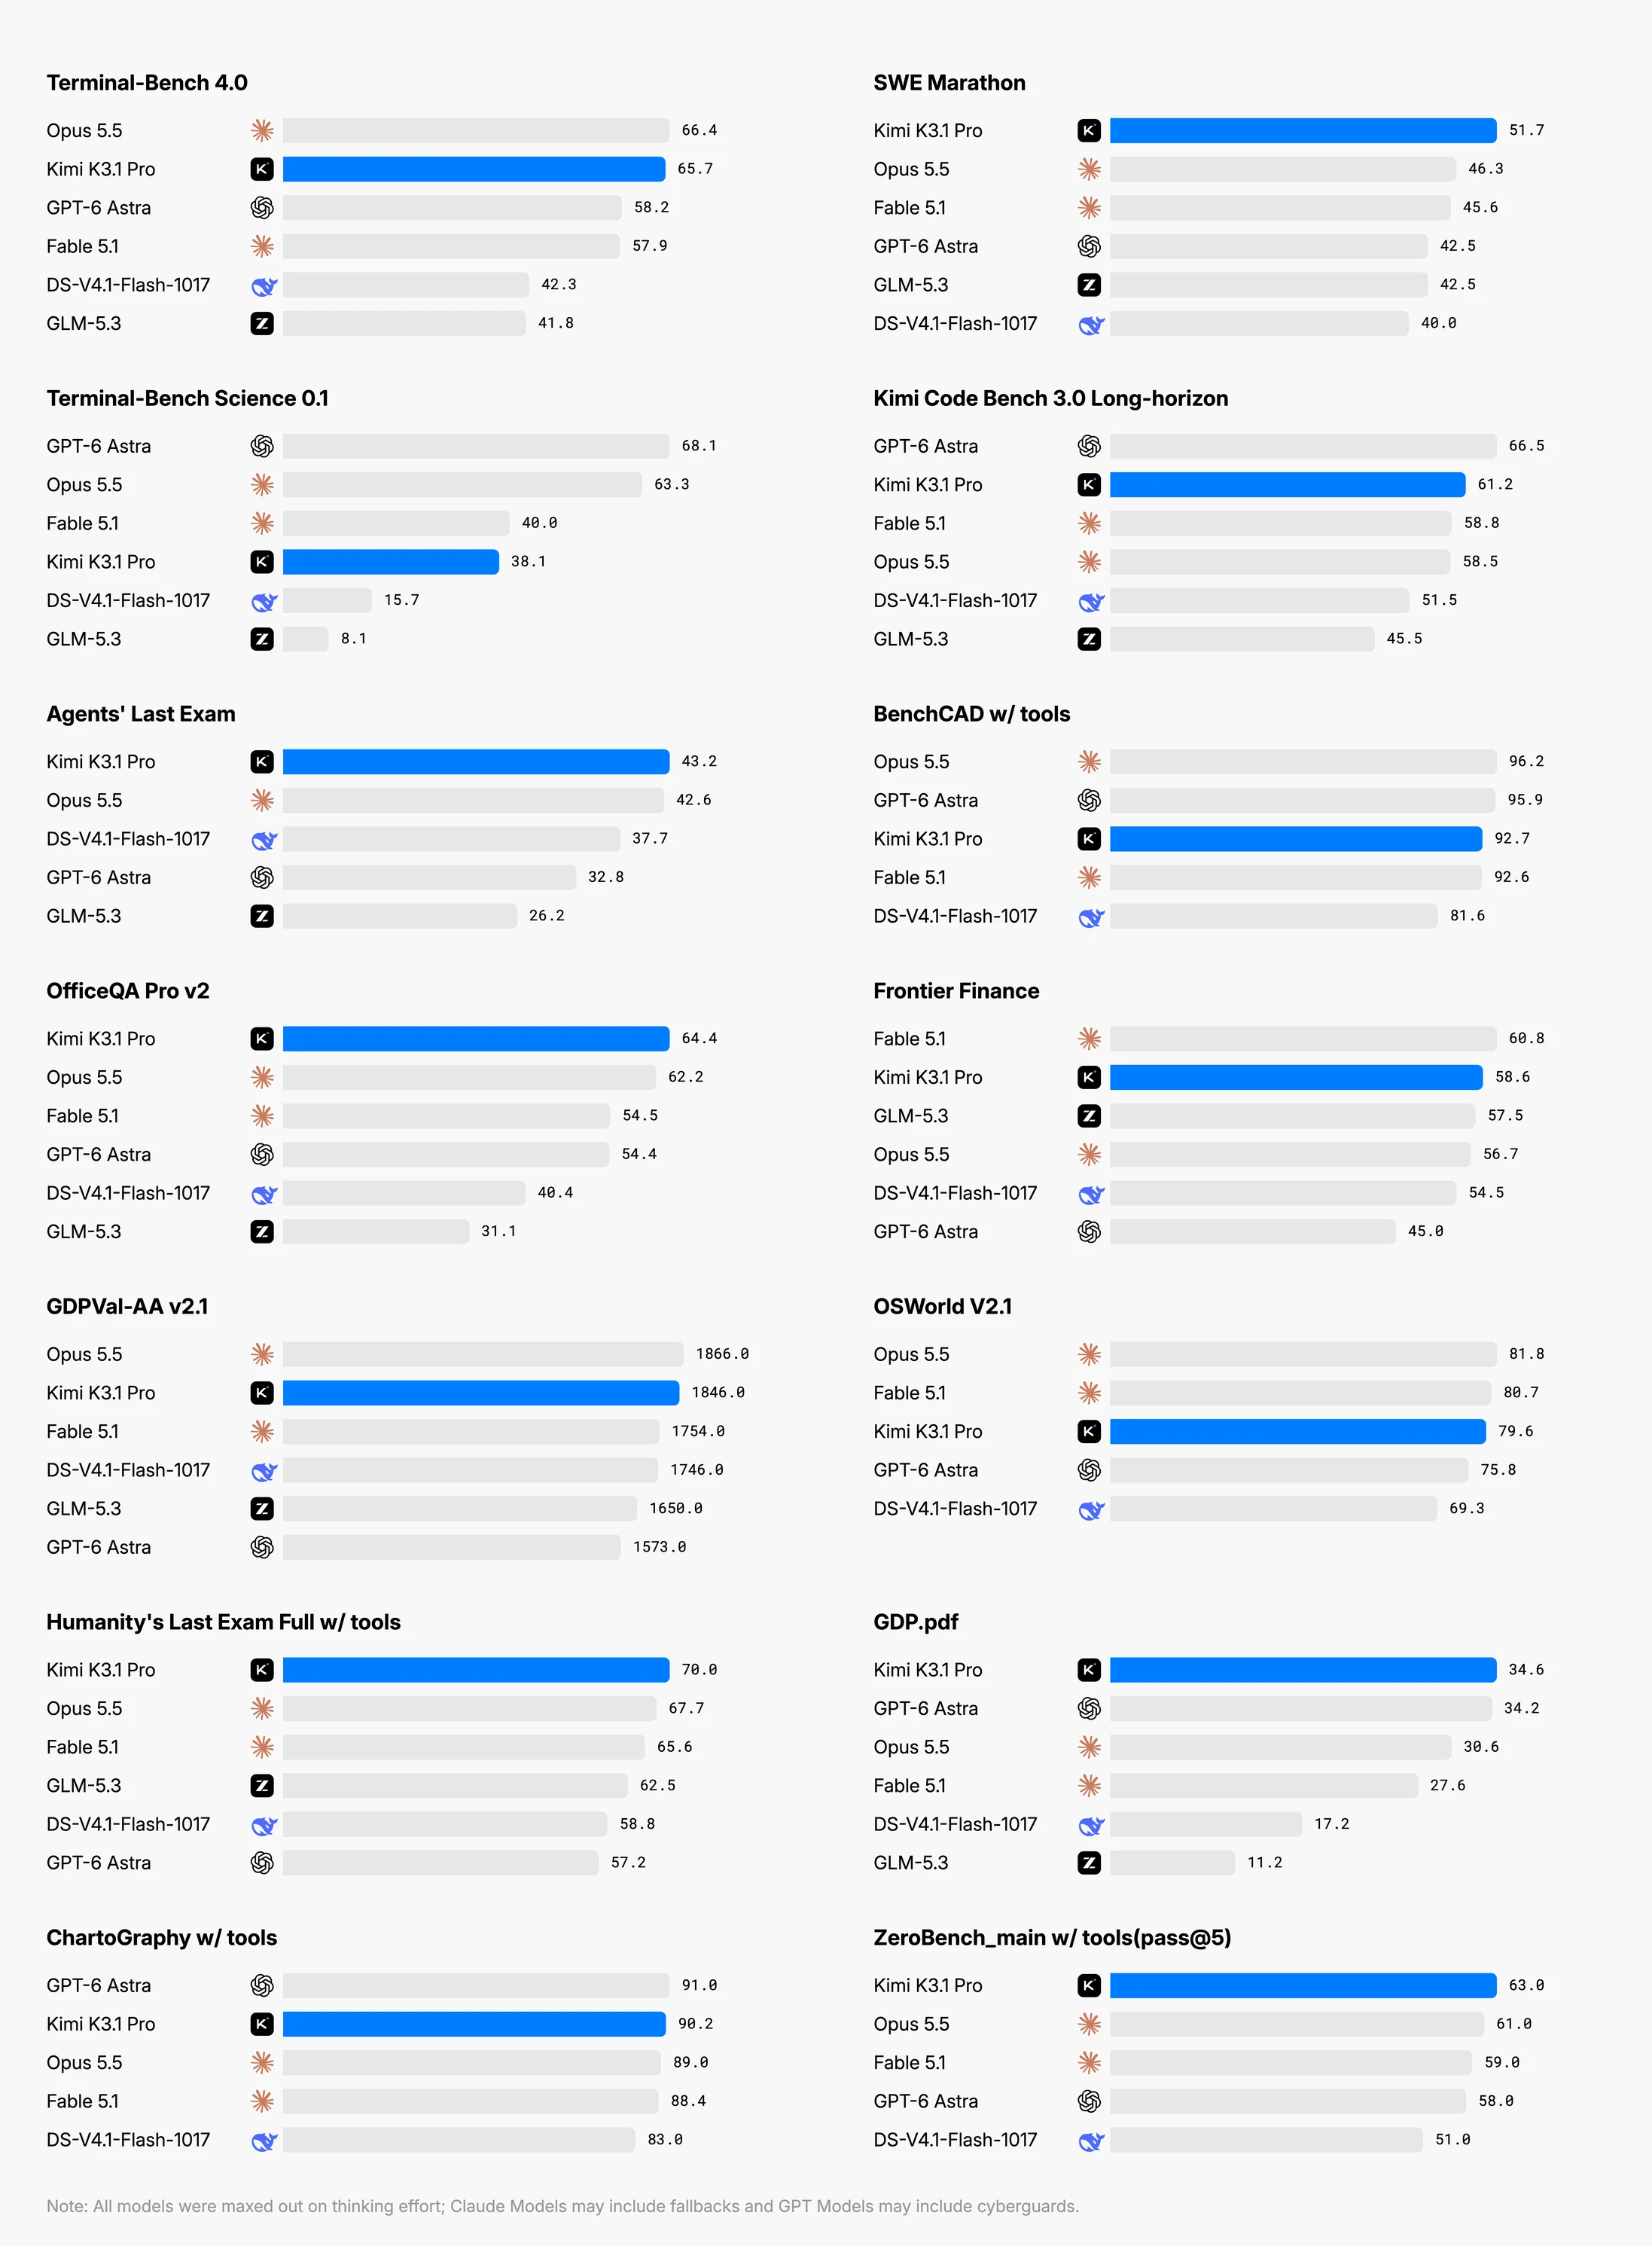
On Terminal-Bench 4.0 it scores 65.7%, ahead of GPT-6 Astra (58.2%) and just behind Claude Opus 5.5 (66.4%). On Moonshot's internal hallucination stress test the claim-level rate fell from 23.4% (K3) to 8.3%. The company says that is a stress test and not a typical daily error rate.
Independent numbers arrived in the thread
Max Woolf, former Senior Data Scientist at BuzzFeed, posted the third-party result: the model scores 55 on the Artificial Analysis Intelligence Index, fourth overall, "beating both GPT-6 Astra and Fable 5.1" and faster than both. The cost is verbosity: it generated 150M tokens during evaluation against a median of 87M.
The cyber-capability sentence
The post says Moonshot aims "not to release open weights that would extend the absolute frontier of cyber capability." One reader read that as an admission: a commenter quoting the passage asked, "So they admit that they could do more, but they won't?" Moonshot's own table shows the effect of the measures: 81.0% on the xdev-bench-hard cyber test at pass@3, against 90.5% for a checkpoint without the reduction measures and 33.3% for K3.
Benchmarks versus daily use
Skepticism came from a reader who had used the earlier models: Kimi models "often" have higher benchmark scores than DeepSeek, Qwen and GLM yet performed worse for them. Another reader tested the new model on a Pac-Man build task and found it ties Sonnet 5.5 at 93 for $0.68 and 11 minutes versus $1.61 and 14 minutes. The practical read: judge it on a task of your own, and budget for the token verbosity.
Get breakdowns like this every day
The top Hacker News stories, unpacked — by email, Telegram, or RSS.
Google's privacy policy update says Gmail and Photos data could feed ads, if you let other services see it
The Verge headline said Google "might" use your Gmail and Google Photos data to target ads. The sentence that matters is the exception clause, and nobody agrees on how hard it is to avoid triggering.