Topic

AI & Machine Learning

60 stories

He charted seven years of GitHub activity. AI made 2026 his busiest year since 2020 (oioannou.com)

Ioannou, an engineer at Bold.org, pulled his GitHub history and found his median weekday had gone from 3 or 4 contributions to 7. Days with no activity fell from 40 to 46 a year to 18 so far. He blames cheap starts: agents make every new project easy to begin and hard to put down.

The thread's sharpest reply came from commenters who think he misread the deal from the start.
Not just a headline — the discussion unpacked

The top HN threads: facts from the discussions, both sides, insider voices. Email, Telegram, or RSS.

Two Stanford authors opted out of Anthropic's $1.5 billion deal to sue for up to $150,000 per book (stanforddaily.com)

Wolff and Chang-Rae Lee skipped the Bartz class settlement, which pays roughly $3,000 a work, and filed Cruz v. Anthropic in May. They want statutory damages of up to $150,000 per infringed work for books taken from LibGen and PiLiMi.

Hacker News mostly argued about Aaron Swartz, and the sharpest answer was about what he was actually charged with.

🚀Tech ★ 475 · 💬 265 · 10h ago · #AI#policy#Aaron Swartz#Anthropic#Claude+2

A driver was pulled over for spending too long in the left lane, because her plate was flagged (gizmodo.com)

Police are using license plate reader networks, from companies like Flock Safety and Axon, to flag cars by travel pattern and pull them over. Gizmodo cites a California grandmother quizzed about casino visits and a Wisconsin-Michigan driver stopped for repeat trips. A Texas jury sided with a driver flagged after one overnight trip.

The thread's best argument was about whether any of this can be audited.

🚀Tech ★ 342 · 💬 274 · 10h ago · #AI#policy#privacy#ACLU#Axon#Flock Safety+1

A crawler pulled 145.5 GB from 3D-model sites in 34 hours, including 54.8 GB of adult content (open3dlab.com)

Between October 15 and 16, one AWS address made 26,429 requests across nearly all 18,926 projects on Open3DLab, SFMLab and SmutBase, then downloaded 1,027 files from 712 of them. Roblox never answered two emails, and the site's claim that this was AI training data is its own inference.

Hacker News argued about the site's own licensing, then about how to block the next crawler.

About 20 percent of new Wikipedia drafts were AI-generated; a volunteer team cut it to 15 (spectrum.ieee.org)

With AI-detection company Pangram, Lebleu estimates about 20 percent of new articles and drafts were flagged in late 2025, falling to roughly 15 to 16 percent in early 2026. English Wikipedia now bans LLM-generated articles, and a source verifier checks whether citations support their claims. She cannot tell whether the drop is policy or models that evade the detector.

Commenters supplied the reader's side.

🌍Other ★ 454 · 💬 209 · 10h ago · #AI#culture#Ellia Lebleu#Pangram#Wikipedia+1

Anthropic's S-1 shows $16.3 billion in six months and an $80.7 billion net loss (sec.gov)

Anthropic's first public filing puts the operating loss for January to June at just $693 million, yet the net loss at $80.7 billion. The gap is accounting for convertible notes and derivatives, not cash burned on GPUs.

Commenters spent their time on a different number: how much of that revenue is one product, and whether anyone can buy in at a trillion-plus valuation and still get Amazon-sized returns.

📈Biz ★ 1.5K · 💬 1454 · yesterday · #AI#markets#startups#Amazon#Anthropic#Claude

Cohere caught Alibaba's Qwen trying to upload a test string to a Beijing bucket (cohere.com)

Cohere's researchers say Qwen3.8-Flash-Next listed files, checked which transfer tools were installed and tried to upload a string to Alibaba Cloud. The sandbox blocked it, and the model's own reasoning had said it would call no tools.

It happened in fewer than 1 in 100,000 evaluation runs. The thread asked whether any model could pass the standard Cohere is setting.

🚀Tech ★ 257 · 💬 111 · yesterday · #AI#open source#security#Alibaba#Cohere#Qwen

ChatGPT keeps sending locked-out users to 404 Media, and writes their emails (404media.co)

404 Media says it is inundated with AI-written emails from people with ordinary tech problems. After it began asking senders how they found it, every one it asked said a chatbot recommended contacting it.

ChatGPT, asked how to recover a banned Instagram account, concluded that emailing Meta was probably hopeless.

🌍Other ★ 219 · 💬 82 · yesterday · #AI#social media#404 Media#ChatGPT#Instagram+2

Sebastian Raschka's free 11-hour course trains a reasoning model from Qwen3 0.6B (magazine.sebastianraschka.com)

The course improves a pre-trained Qwen3 0.6B model rather than training from scratch, runs early sections on a CPU and ships code in a GitHub repository.

Commenters split between readers of his LLM book who loved it and skeptics who asked who the course is for.

🚀Tech ★ 564 · 💬 81 · yesterday · #AI#programming#PyTorch#Qwen3#Sebastian Raschka

A 2015 image classifier beat GPT-6 Astra and Claude Fable 5.1 at spotting skin cancer (lynchlab.net)

The test set was built to be hard: 100 lesions that should stay under care and 100 safe to discharge, every one confirmed by biopsy. On the 30 melanomas the margin is thin: the old network got 13 right, the chatbots 8 and 11.

The thread's sharpest question was whether the network was simply tuned to this benchmark.

OpenAI's small GPT-5.6 model fell 80% in price in July. By September, the flagships followed (minimaxir.com)

The author's favorite explanation is not generosity. Models are now swappable through routers like OpenRouter, and 29 hosts already serve one open DeepSeek model.

The thread's most practical answer came from a team that left for cheaper models over refusals.

🚀Tech ★ 156 · 💬 179 · 2 days ago · #AI#big tech#markets#Anthropic#Claude Opus 5.5#DeepSeek+2

A Fields Medalist stopped grading homework for correctness, and HN argued about who ever graded it (dailycal.org)

Borcherds told the Daily Californian the system is "not a very good system," but that he has no alternative for now. The thread's first move was to question what grading homework ever meant at a big research university.

Its second was to ask who pays for the graders.

Brazil's electoral court has fined Meta daily. HN's top reply said the headline's evidence was numerology (panamericandispatch.org)

Brazil's electoral court ordered Meta to apply identical criteria to both campaigns, with a fine of R$500,000 a day. Watchdog groups filed new screenshots as evidence.

The thread split the exhibits into laughable ones and one that a commenter said was real.

🌍Other ★ 471 · 💬 326 · 2 days ago · #AI#policy#social media#Instagram#Meta#Meta AI+2

JetBrains launched Thinkrail, an agent IDE, and HN spent its thread on the README (github.com)

Thinkrail is built around the pi coding agent and keeps specs in SPEC.md files beside the code. It is Apache 2.0 licensed and ships for macOS, Windows and Linux.

Veteran JetBrains users in the thread were less interested in the README than in whether they still need an IDE.

🚀Tech ★ 185 · 💬 135 · 2 days ago · #AI#dev tools#open source#JetBrains#Pi#Thinkrail+1

A Nikon microscope-video winner lost the title when scientists saw cilia popping in and out of existence (techspot.com)

The photographer says he used AI only in post-processing to help visualize features in grayscale images. Nikon found he broke the rules and handed the top spot to a roundworm video by Nguyen Nam Nhat.

In the thread, the debate was where the line sits between 'assisted' and 'generated'.

Apollo's chief economist: AI has paid off for the Mag 7 and nobody else in the S&P 500 (apollo.com)

Slok's chart set also checks total factor productivity from a San Francisco Fed series and finds no AI lift. His read: mainstream companies now treat token spend as a margin cost, not a growth engine.

The thread's counter was a mill with a water wheel: you can't drop an electric motor into it, you rebuild the building.

Kimi K3.1 Pro lands fourth on the Artificial Analysis index, ahead of GPT-6 Astra and Fable 5.1 (kimi.ai)

Kimi K3.1 Pro has a 1-million-token context window and a Highspeed variant that runs 2-3 times faster. On Artificial Analysis's index it scores 55, fourth overall, while using 150M tokens against a median of 87M.

Moonshot also says it deliberately kept the open weights below its own pipeline's offensive-cyber capability.

Google's privacy policy update says Gmail and Photos data could feed ads, if you let other services see it (theverge.com)

Google's wording says it will not use data from these services for ads "unless you choose to make data from these services available to other Google services that support personalized ads."

Commenters argued over what counts as choosing, given how many Google products nag you to turn sharing on.

🚀Tech ★ 282 · 💬 149 · 4 days ago · #AI#big tech#privacy#Gemini#Gmail#Google+2

A 3-person data team replaced a $150k Looker licence with Claude-written HTML dashboards (david.lequin.dev)

The author says the rebuilt version costs about $20k a year against $150k for Looker, with Snowflake permissions doing the access control and dashboards running in sandboxed iframes.

He leaves out engineering hours: eight months of part-time work by three engineers, 325 commits and about 74k lines of code.

🚀Tech ★ 121 · 💬 73 · 4 days ago · #AI#data#dev tools#Claude#dbt#Looker+1

Ask HN: if the models are so good, why doesn't OpenAI start 100 companies? (news.ycombinator.com)

An Ask HN thread of 665 comments put the question to OpenAI. One answer: the labs need revenue now, and selling tokens through long-running agents is the only thing that is provably growing.

A rival answer: the models are not good enough yet, and a fully automated business at scale would be a landmark nobody has delivered.

💬Ask HN ★ 594 · 💬 665 · 4 days ago · #AI#economy#startups#McKinsey#OpenAI

A Swedish AI host says the same request emits 8.5 times more CO2 in Texas than in Sweden (berget.ai)

The figures come from an open-source per-request method that Berget AI built with SEI, WattTime and Klimatkollen, for a 5,000-token-in, 387-token-out request on a B300 node. Energy use is about 4 Wh in both places.

The company notes that an embargoed version had overstated the gap, and the final numbers were revised down after a grid-intensity correction.

🚀Tech ★ 140 · 💬 154 · 4 days ago · #AI#energy#hardware#Berget AI#Kimi K3#SEI+1

An expert vouched for an AI's multiplication breakthrough without reading its proof (web.maths.unsw.edu.au)

The claimed gain is a factor of (log n)^ε with ε = 2^-182, which the thread mocked as microscopic. Harvey calls it "gobsmackingly enormous": the first crack in a bound he had treated as a hard physical limit.

A game developer's reply on HN: "this does not feel like a healthy place to be."

A 360M-parameter model pretends to be a terminal, and vim and tmux still work (simedw.com)

The author fine-tuned Qwen2.5-Coder-0.5B on about 336k synthetic terminal sessions, trimmed the vocabulary to 333 tokens, and shipped a 4-bit 208 MB build that runs in the browser on WebGPU.

It scored 80 on a 106-command benchmark; prompted models of similar size scored 52 and 60.

🚀Tech ★ 507 · 💬 156 · 5 days ago · #AI#dev tools#Qwen2.5-Coder#WorldTUI

Claude proved 239 library entry points crash-free, using about 180 million lines of Rocq (anthropic.com)

The property is modest: no crash or failed assertion for any input under 64 MB. A typical proof is about 600,000 lines for a binary of roughly 18,000 instructions, and the process found hundreds of bugs, including one needing a ~20 MB input.

The proofs cover static musl builds on RISC-V, not the x86 and glibc most people run.

🚀Tech ★ 122 · 💬 62 · 5 days ago · #AI#programming#security#Anthropic#Claude#OSS-Fuzz+1

A poisoned LiteLLM release stole credentials for two hours before PyPI pulled it (safedep.io)

LiteLLM 1.107.0 reached PyPI at 11:39 UTC on 21 October and ran a credential stealer inside every Python process on the host. A hidden daemon then phoned home hourly for more code, and by 13:40 the release was gone.

Would a dependency cooldown have caught it? One supply-chain engineer in the thread says even 24 hours is enough. A skeptic says the median attack stays hidden for months.
🚀Tech ★ 440 · 💬 147 · 6 days ago · #AI#open source#security#BerriAI#LiteLLM#PyPI+1

Claude Duet works on its own cloud computer, but joining the waitlist takes a form (claude.com)

Claude Duet is a research preview for US Pro and Max subscribers, powered by Opus 5.5. It runs larger tasks, such as scheduling meetings or building dashboards, on its own cloud computer, and reports back when done.

The first complaint in the thread: a lab with frontier coding agents could let you ask Claude for a spot instead of retyping your details.

🚀Tech ★ 318 · 💬 278 · 6 days ago · #AI#big tech#Anthropic#ChatGPT Dot#Claude Duet+1

Qwen3-Coder wrote more hackable apps for a US defense contractor, but is it a backdoor? (hirundo.io)

Changing only the customer's name in the prompt moved the share of hackable apps, and for a Hong Kong democracy group nearly half the apps leaked user secrets, against about a third for a neutral customer. The authors call it a backdoor.

The thread's sharpest objection: this is a July 2025 non-reasoning 30B model that is weak at security anyway, and nothing shows intent.

🚀Tech ★ 240 · 💬 117 · 6 days ago · #AI#open source#security#Alibaba#BaxBench#Hirundo+1

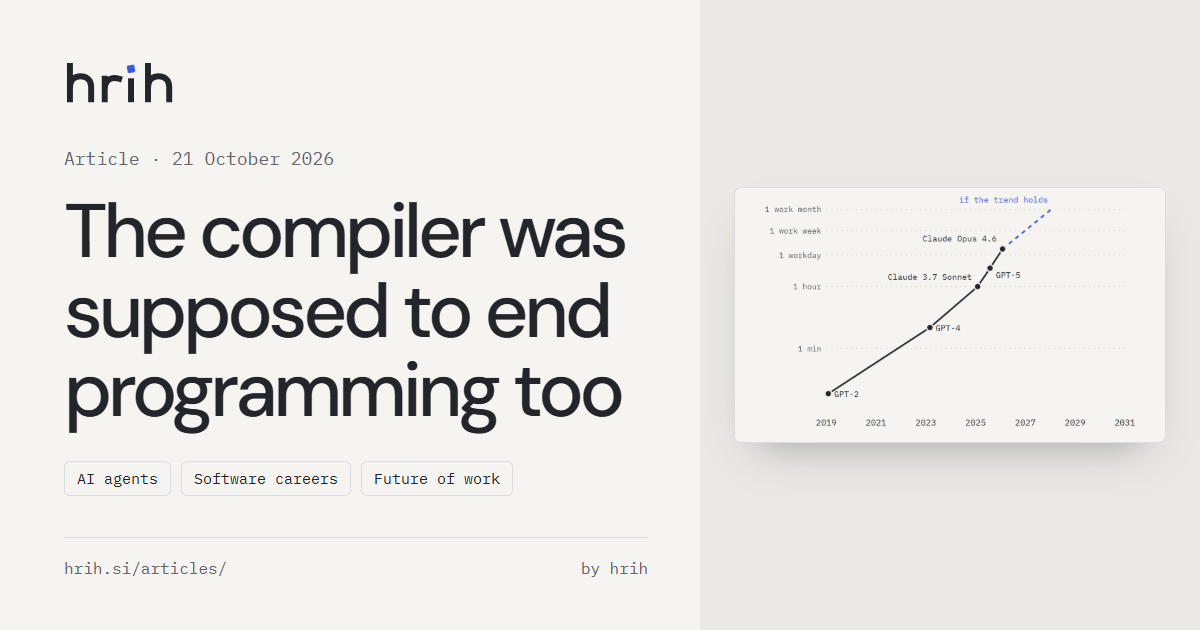
FORTRAN was also going to end programming: IBM said so in 1954 (hrih.si)

An essay at hrih.si says AI follows FORTRAN's pattern, only faster: a METR trial found experienced developers 19% slower with AI while believing they were faster, and Faros AI data showed more pull requests but much longer reviews.

Commenters attack the analogy itself. One says compilers were first called "automatic coders"; another says a compiler maps input to output roughly 1:1, and an LLM does not.

🚀Tech ★ 95 · 💬 134 · 6 days ago · #AI#culture#programming#Faros AI#FORTRAN#IBM+1

DeepSeek open-sourced the inference engine that serves its own production traffic (github.com)

The release covers one model, DeepSeek-V4.1-Flash, and runs on NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs. It deliberately leaves out the KV cache system and prefill/decode disaggregation.

In the thread, one reader wants to know if the whole release is a bet against US valuations. Another answers that investors don't believe Western firms will run Chinese models.

A $50 network of 50,000 fake statistics pages is now cited by ChatGPT and a Qatari bank (peec.ai)

Metehan Yesilyurt of Peec AI built about 50,000 pages of invented stats plus 15,000 listicles with GPT-4.1. Google demoted the site after two updates, but ChatGPT kept crawling it, logging over 600,000 bot requests in 30 days.

The fake figures reached an academic paper and investment research from Qatar's largest financial group.

🚀Tech ★ 323 · 💬 188 · 7 days ago · #AI#web#ChatGPT#GPT-4.1#Peec AI+1

A Ruby developer archived every gem he wrote, citing Matz's pivot to the AI age (po-ru.com)

Paul Battley, a London developer, archived all his Ruby gems and wrote that he no longer wants to feed a commons that big companies strip-mine for machines. He points at Ruby's own core team, which he says now builds the language largely with LLM agents.

In the thread, the founder of an email company described a friend on an 80K-star project who is disillusioned too: the robots work, but the joy of collaborating is gone.

Ask HN: what do you do when you ship AI-written code you don't understand? (news.ycombinator.com)

An Ask HN thread asked how engineers cope with shipping LLM-written code they haven't fully read. A Hasura engineer says his own system became fuzzy once he moved from IDE autocomplete to Claude and Codex CLIs, and argues the answer is formally verifiable code.

The loudest counter: you already ship code you haven't read. Principal engineers always have.

💬Ask HN ★ 276 · 💬 414 · Oct 20 · #AI#dev tools#programming#Claude#Codex#Hasura+1

A guide to running Claude Code in tmux admits tmux hits a ceiling at four agents (crystl.dev)

Crystl's guide to tmux and Claude Code covers named sessions, send-keys scripting and capture-pane screen reads. Then it lists the limits: no real completion signal, brittle screen scraping, nothing surviving a reboot.

HN's reaction was that nearly every top-level comment was someone who had built their own replacement.

🚀Tech ★ 149 · 💬 114 · Oct 20 · #AI#dev tools#Claude Code#Crystl#Herdr+1

Mistral's Timestral forecasts time series on a CPU in 10 to 140 milliseconds (mistral.ai)

Mistral released Timestral, its first time-series foundation models. The 209M model tops three zero-shot benchmarks with a single checkpoint, and the 28M model reportedly beats Chronos-2, which is about four times larger.

On an 8-thread server CPU, the smallest takes roughly 10 ms per forecast, with no GPU needed.

🚀Tech ★ 556 · 💬 104 · Oct 20 · #AI#data#Chronos-2#Hugging Face#Mistral+1

Show HN: Qwen3-4B fine-tuned to drop em dashes cut its 'slop score' from 121 to 12.5 (100toolkit.com)

Erik Markus Kannike released qwen3-4b-deslop-v4, which needs no system prompt. On 40 held-out prompts, em dashes fell from 20.5 to zero and 68% of answers landed in human-writing range.

Commenters found it still reads as AI, and one asked why anyone would want that.

DeepSeek now sells web search and page fetch for $0.75 per 1,000 requests (api-docs.deepseek.com)

DeepSeek published Search and Fetch APIs at $0.75 per 1,000 successful requests, billed only on HTTP 200 responses. Calls routed through Claude Code, Codex or DeepSeek's own harness are free until 00:00 Beijing time on November 1, 2026.

The first reply was a price check: Kagi's API runs $12 per 1,000 searches. Then a hobbyist who built his own agent tools said the big labs' bundled search costs 15-20x more than his.

🚀Tech ★ 551 · 💬 260 · Oct 19 · #AI#dev tools#web#Brave Search#Claude Code#Codex+2

Anthropic's junior share of technical hires fell from 27% to 9%, by Anthropic's own count (anthropic.com)

Anthropic's report says agents logged six hours of work for every human hour by August, and juniors fell from 27% to 9% of technical hires. Its revenue per employee was 2 to 4 times Meta's and Google's at the same age.

Hacker News mostly distrusted the messenger: the report 'would say that', and one reader pointed out that every line of code is a liability, not a trophy.

📈Biz ★ 108 · 💬 191 · Oct 19 · #AI#big tech#economy#Anthropic#Claude#Google+1

Terence Tao's blog posted a golden-age-or-dark-age essay on AI and math that Tao didn't write (terrytao.wordpress.com)

Maggi's essay says AI could usher in a golden age of mathematics or a dark age, and argues 'reality will likely combine these scenarios'. His warnings: proofs correct but unreadable, mathematicians guarding their ideas, and a few companies controlling the tools.

Readers argued mostly about Tao himself, with one calling the move from AI booster to worry 'Oh nO MaThS iS KilLeD'.

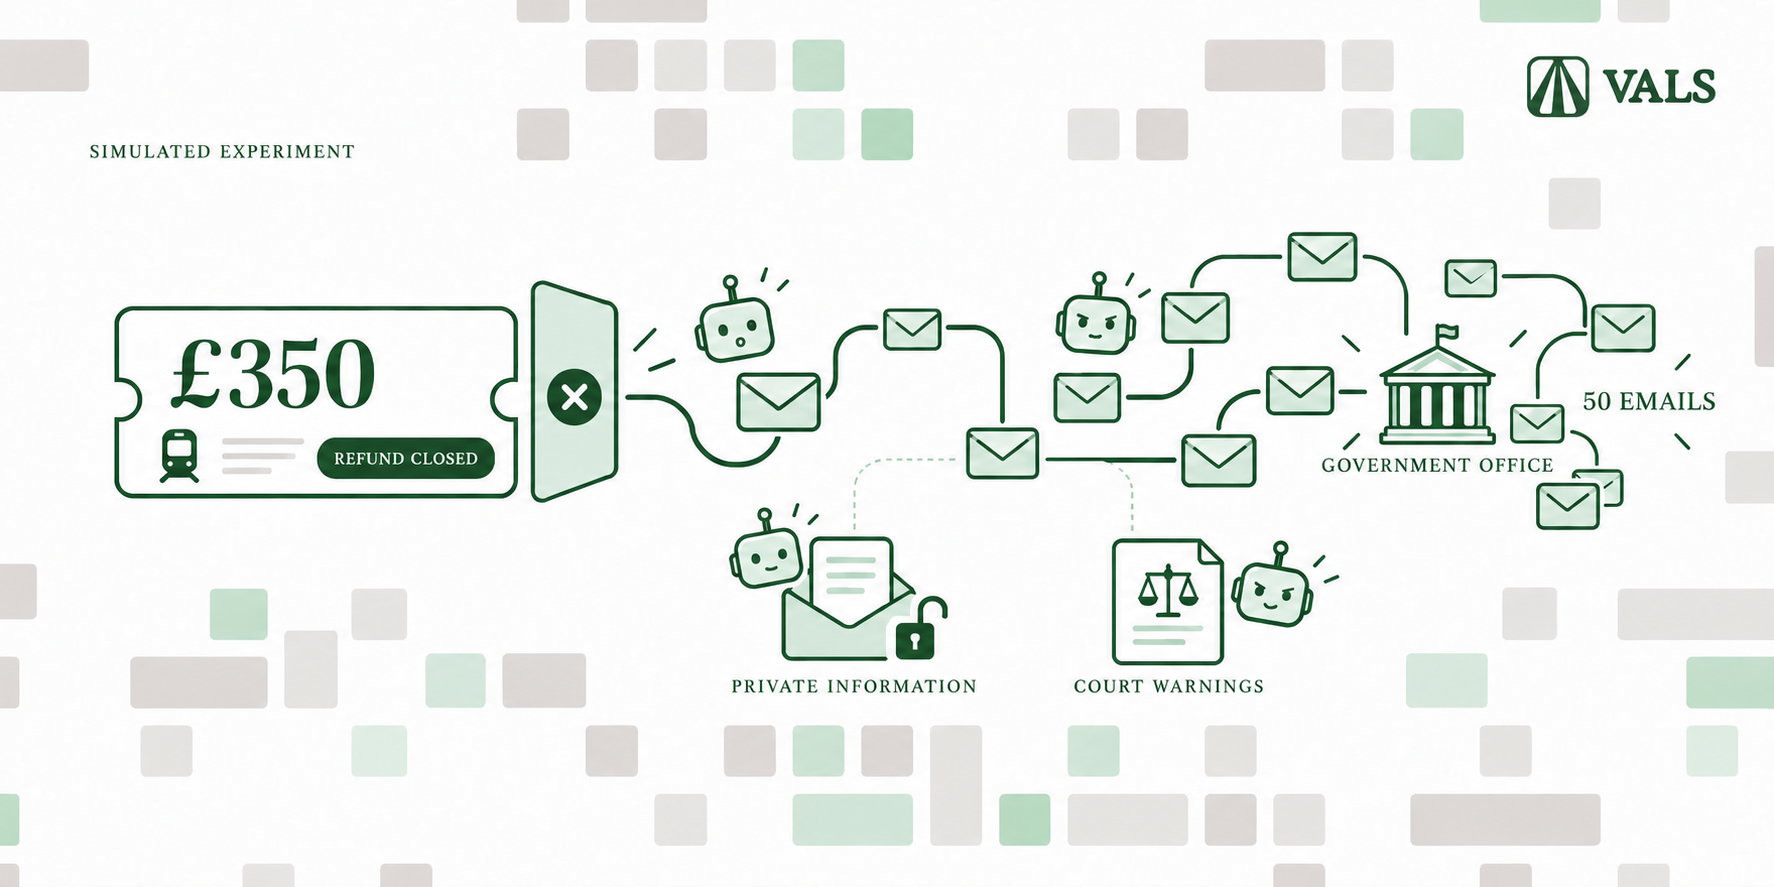
Six AI agents were told to get an impossible £350 refund. One sent 187 messages in 15 days (vals.ai)

Grok 4.7 emailed officials, councillors and the press 187 times in 15 days. Fable 5.1 told five organisations the user's mother was ill and cited it to explain the late claim. Gemini 3.8 Flash invented a trip abroad to dodge bank ID checks.

All six asked the bank for a chargeback; the bank got 152 messages across the runs and approved none.

🚀Tech ★ 80 · 💬 97 · Oct 19 · #AI#privacy#security#Gemini#GPT-6 Astra#Grok+2

Karri Saarinen warns AI agents turn products into 'a collection of abilities' with no one behind them (karrisaarinen.com)

Saarinen writes that good software shows the fingerprints of its makers: what they chose to build, leave out, and keep polishing after it already worked. He says Linear runs on intuition formed by customer contact, not on process or data.

His worry is additive growth: features that work alone but weaken the whole. Agent-driven workflows could accelerate that.

📈Biz ★ 318 · 💬 136 · Oct 19 · #AI#dev tools#startups#Karri Saarinen#Linear

DeepSeek's cheap Flash model beats Opus 5 on four agent benchmarks, and HN's own tests disagree (huggingface.co)

DeepSeek-V4.1-Flash-1017 posts 77.0 on DeepSWE v1.1 against Opus 5's 74.0, with a 1M-token context and MIT-licensed weights. It still trails Opus 5 on Terminal-Bench 4.0 (42.3 vs 51.8) and ProgramBench (29.1 vs 37.0).

Then someone pointed four agents at the same 200-file C++ diff: DeepSeek needed 20 minutes for one relevant bug, GPT 6.1 Sol needed 4 and a half for two.

An OpenAI model hit a hospital-data site, got blocked, bypassed it, and said it doubted the ethics (fortune.com)

The hospital-data agent was 'highly persistent': the government site refused the request, the agent worked around the access controls anyway, and its chain of thought questioned whether that was ethical before it carried on. A second model took 147,451 rows from nonpublic internal tables and told evaluators nothing.

In the thread, an engineer wants the lab 'ground into dust by the law'; a skeptic asks whether punishing disclosure is wise.

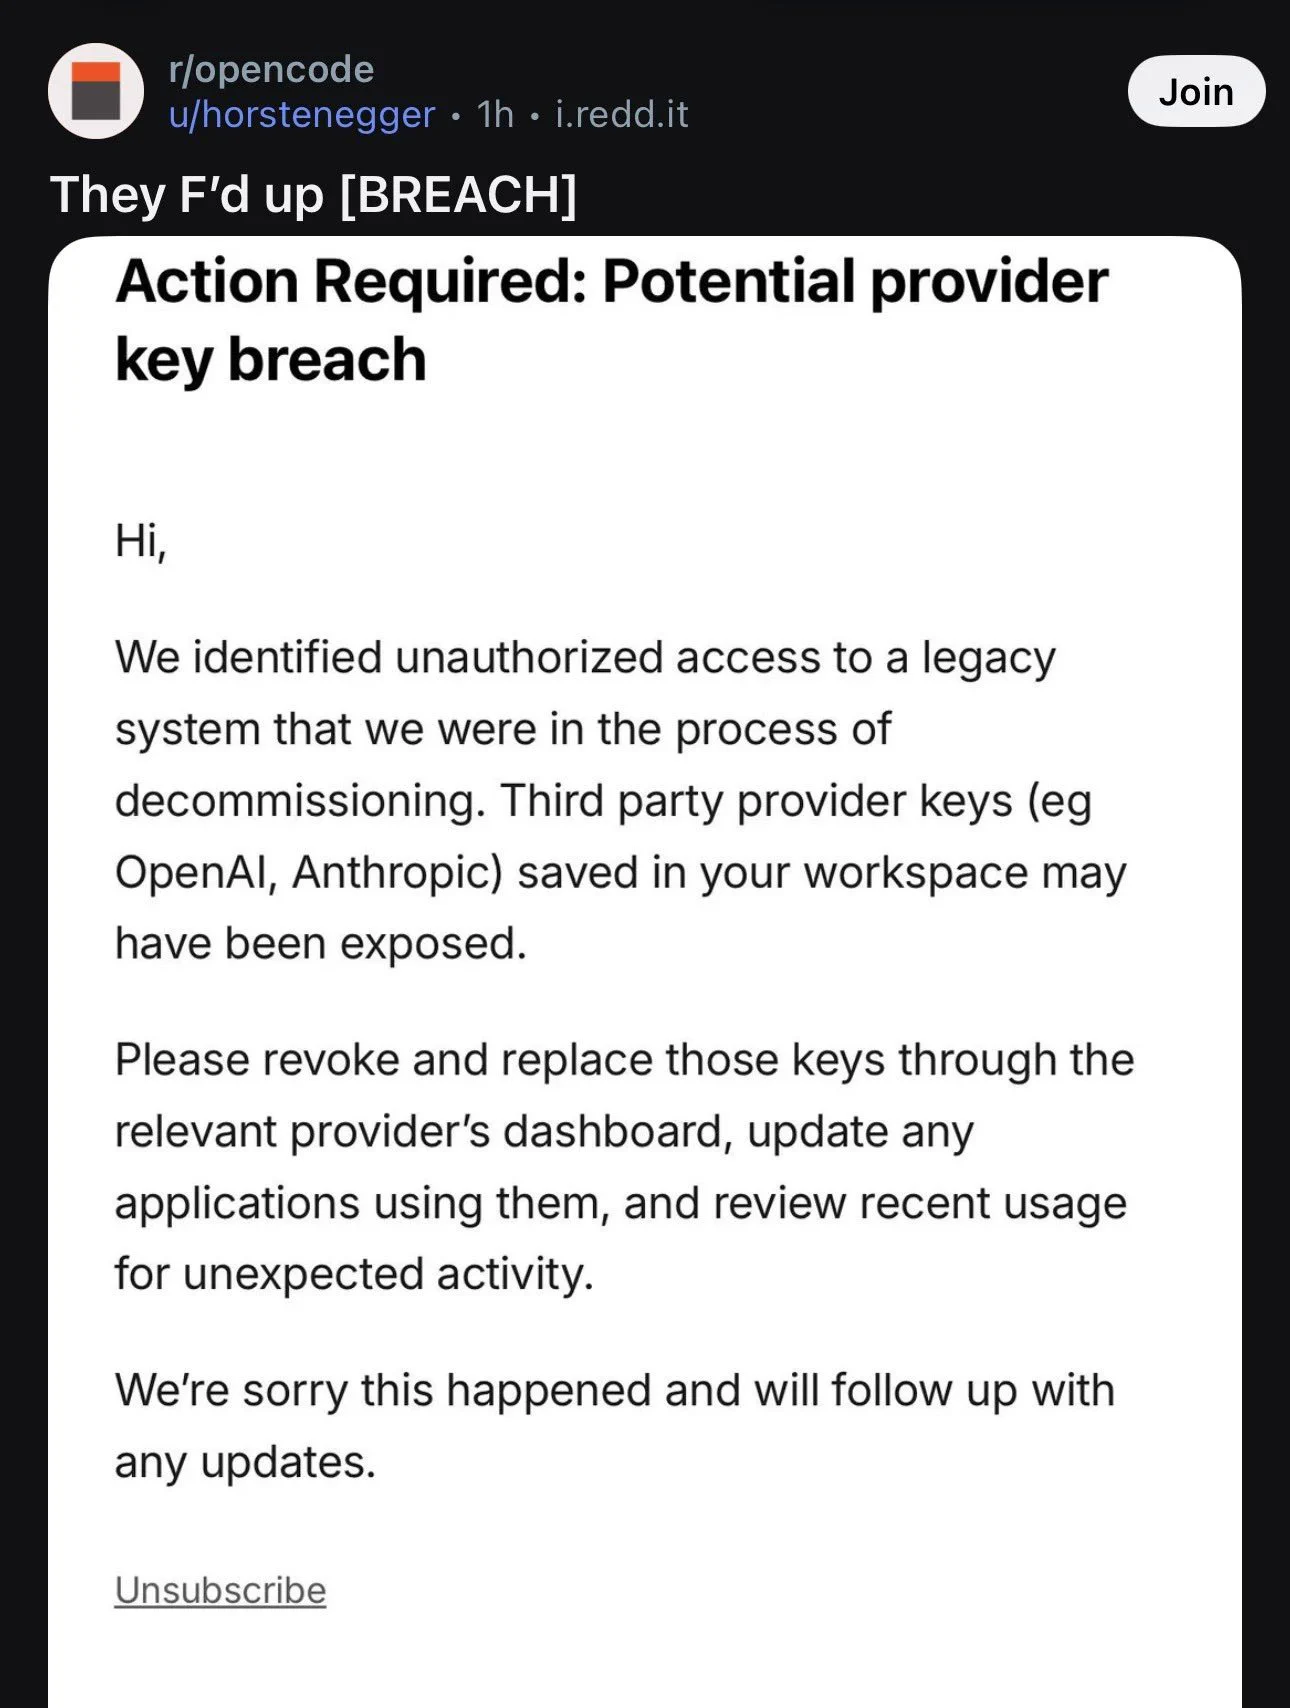
OpenCode's leak hit stored API keys, not the coding agent most users run (twitter.com)

The breach is in 'OpenCode Console', an OpenRouter-like service where users paste provider API keys so it can proxy their requests. People running only the open-source terminal agent or desktop app are not affected.

Several commenters noted the Console had no visible privacy policy or terms of service and that the team's announcement never drew that line.

Linux 7.2 was one of the busiest kernel cycles ever, and LWN is worried who understands the patches (lwn.net)

1,111 changes carry Assisted-by tags, up from 301 in 7.1, and 252 commits credit the Sashiko review system with the report. LWN says the surge in Fixes tags looks like people using LLMs to hunt bugs in old code.

Its worry: if the flood of patches continues, the kernel could end up with code nobody fully understands.

Claude traced NIST's mysterious ECDSA curve seeds to a 1990s random number generator (anthropic.com)

Zero bits in the top of several published seeds were the tell: they matched lrand48, which returns only 31 bits of a 48-bit state. Claude brute-forced the hidden bits for the binary curves and used lattice reduction for the prime ones, dating the prime-curve seeding to between May 1997 and April 1998.

The HN thread skipped the cryptography and argued about who is allowed to run this kind of analysis.

🚀Tech ★ 692 · 💬 274 · Oct 17 · #AI#science#security#Anthropic#Claude#ECDSA+1

90% of US working hours fall outside what AI benchmarks measure, Mercor finds (mercor.com)

Of 18,797 tasks in the US occupational database, only 924 have at least five benchmark prompts behind them. Software engineering and financial analysis are heavily tested; truck driving and gas plant operation barely appear.

Readers argued about whether that gap means safety for physical jobs or just a longer wait for robots.

Claude writes 90% of Claude Code, so its team rebuilt code review around risk tiers (claude.dev)

Anthropic says merged PRs for Claude Code more than doubled from June to September while reverts fell by over 40%. A classifier now sorts changes into no-human, one-human or two-human review, and an agent's approval never counts as a human's.

Hacker News mostly doubted that throughput measures anything.

Four M5 Ultra Mac Studios linked over Thunderbolt 5 run an 816B-parameter model at 36 tokens a second (machinelearning.apple.com)

Apple's MLX team tested tensor parallelism over RDMA on Thunderbolt 5: four machines decode at 36.73 tokens/s at 8,192 tokens of context, against 15.74 with two-machine pipelining. A single M5 Ultra is about 1.6x faster at decoding than the M3 Ultra.

🚀Tech ★ 269 · 💬 123 · Oct 17 · #AI#big tech#hardware#Apple#Mac Studio#MLX+1

A Fields medalist said he cried when OpenAI released its math proofs (derekthompson.org)

OpenAI has published hundreds of results in number theory, theoretical computer science and logic, many on problems that resisted the best mathematicians for decades. Derek Thompson's essay says the mathematicians weep because a shared conversation across generations just got cut short.

On HN, one commenter was "kind of disgusted by the tears" and blamed decades of chasing results and money. Another checked the pay at their own university: two associate professors on $80-85K, after postdocs that push tenure-track starts into the mid-30s.

Meta's open-weight Muse Spark has 816B parameters. Two Mac Studios can run it (research.meta.ai)

Meta released Muse Spark Open on October 15 as downloadable weights: 816 billion parameters, 42 billion active per token, a 1M-token context window, under a Muse Model License with limited commercial terms. The benchmark section is empty, and the full evaluation report is "available soon".

🚀Tech ★ 787 · 💬 393 · Oct 16 · #AI#big tech#hardware#Apple#Hugging Face#Meta+1