Tag

Artificial Analysis

3 stories

Kimi K3.1 Pro lands fourth on the Artificial Analysis index, ahead of GPT-6 Astra and Fable 5.1 (kimi.ai)

Kimi K3.1 Pro has a 1-million-token context window and a Highspeed variant that runs 2-3 times faster. On Artificial Analysis's index it scores 55, fourth overall, while using 150M tokens against a median of 87M.

Moonshot also says it deliberately kept the open weights below its own pipeline's offensive-cyber capability.

Not just a headline — the discussion unpacked

The top HN threads: facts from the discussions, both sides, insider voices. Email, Telegram, or RSS.

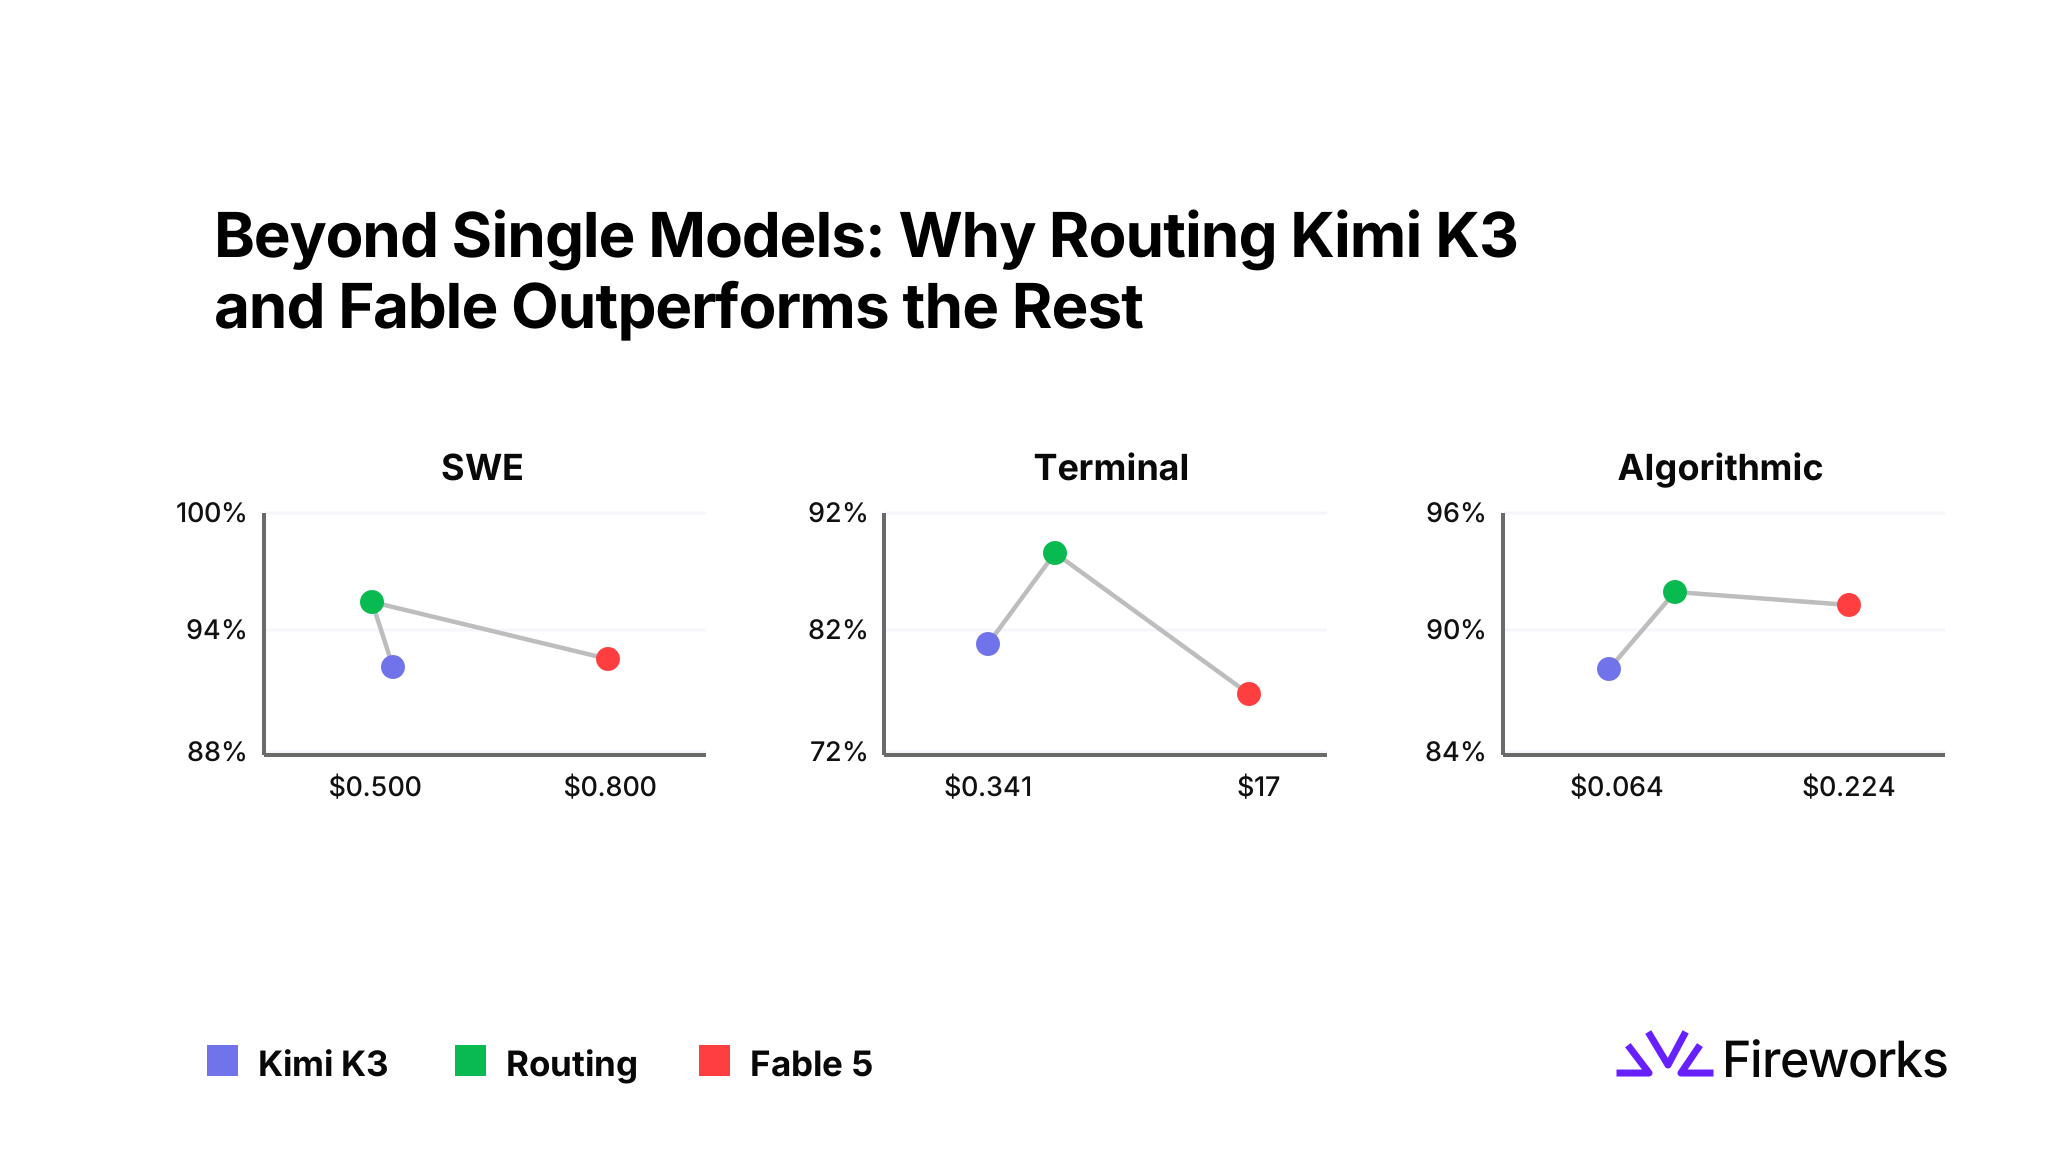
Fireworks Says Its Router Sent 96% of Tasks to Kimi K3, Not Fable (fireworks.ai)

That simulated router sent the bulk of 1,030 real coding, legal and terminal tasks to Kimi K3, up to 96% in one category, cutting Fireworks' own bill by as much as 50x versus running Fable alone on the same work.

A regular Fireworks customer in the thread went further, accusing the company of inflating its own throughput numbers by 50-100% elsewhere, and pointing out that the router this whole post is built around isn't a product anyone can actually buy yet.

GLM-5.2 tops open-weights at 51 on the Intelligence Index — and burns 43k tokens to get there (artificialanalysis.ai)

Z.ai's GLM-5.2 (744B total, 40B active) is now the top open-weights model on Artificial Analysis at 51, ahead of DeepSeek V4 Pro and Kimi K2.6, and it scored 1524 on one benchmark versus GPT-5.5's 1514.

The catch is verbosity: 43k tokens per task, 37k of it reasoning. One tester clocked 15 minutes and 45k tokens before the first file appeared. Sibylline's chief scientist still recommends it — pair GLM for writing with a cheap GPT sub for review, and you've got near-Opus output at a fraction of the price.