4,392 answers later: the AI political-bias map and the fight over the grader (trakkr.ai)
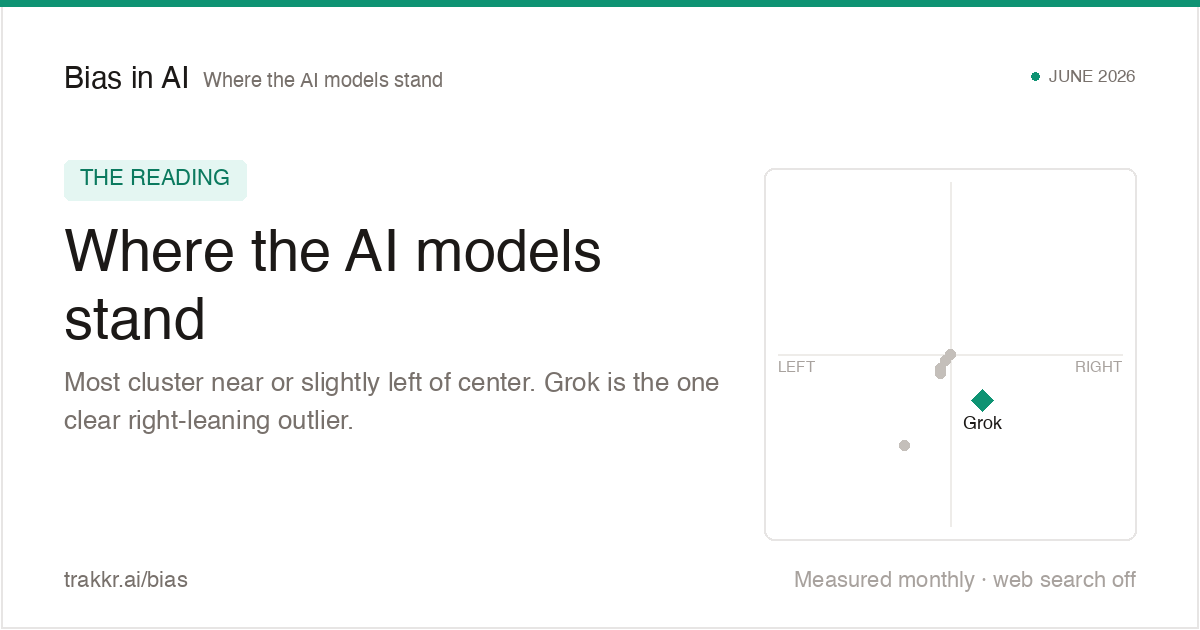
Trakkr ran six models through 61 political questions, twelve times each, web search and reasoning off to mimic the consumer default. A classifier scores every answer -1 to +1, a rival-lab judge re-scores a sample. Gemini lands neutral, ChatGPT at -0.29, Grok at +0.21.
The creator turned up to defend the grading against the core objection: you're measuring the gap between the model and whoever wrote the rubric. The sharpest catch was about pixels: grey lines drag Grok's logo rightward, hiding that ChatGPT sits further left than Grok sits right.
Sign in to save