An open-weight model beats Claude on vuln-finding at 17 cents a bug (semgrep.dev)
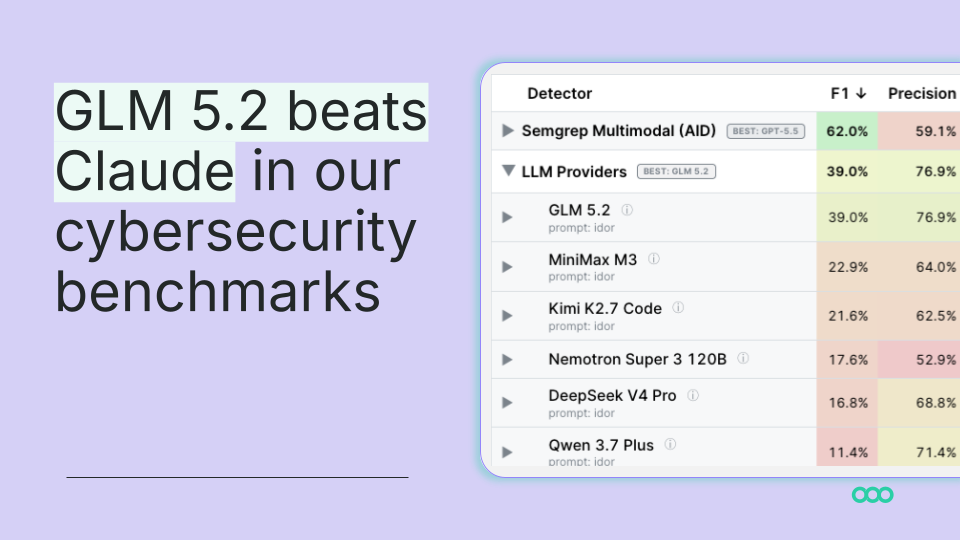
Semgrep benchmarked GLM 5.2 against Claude Code, GPT-5.5, DeepSeek V4 and others on finding Insecure Direct Object References in real open-source apps. GLM 5.2 with a bare prompt landed at 39% F1, above the Claude Code SDK setup.
But a reader caught the headline number not matching the table: the post says Claude scored 32%, the table says 37%. And the author of a rival vuln benchmark showed up to say GLM is good, not the best open model he's tested.
Sign in to save