Overlapping CPU bookkeeping with GPU math bought Moondream 35% more throughput on a B200 (moondream.ai)
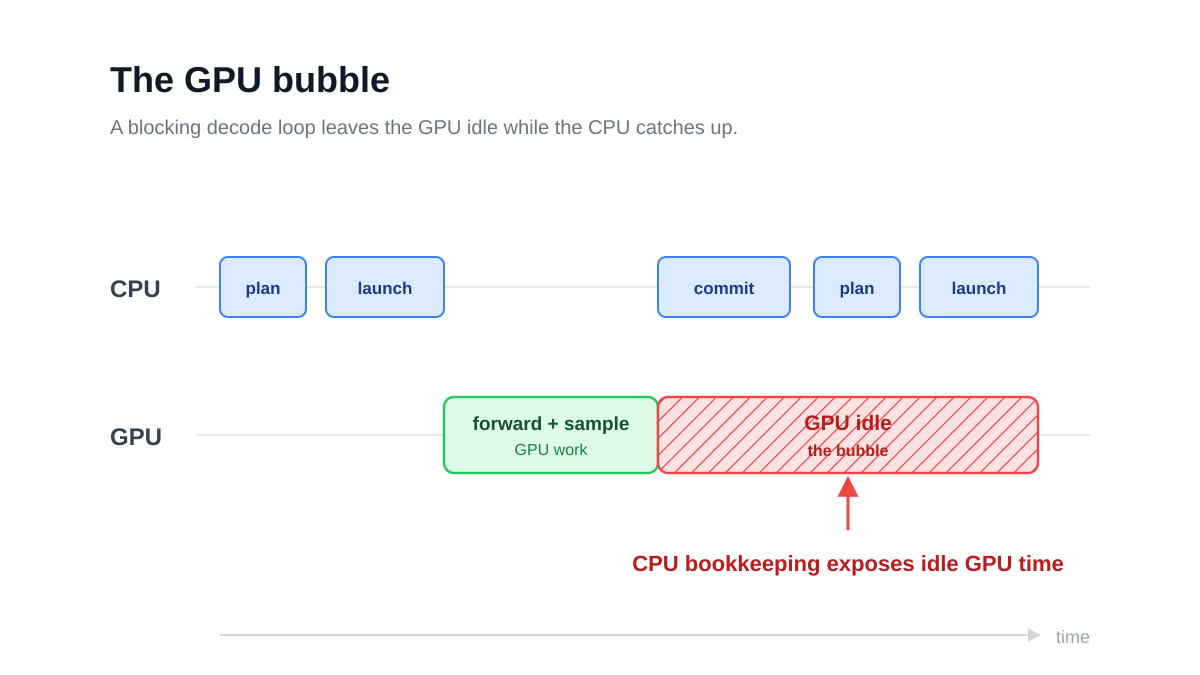
In LLM token generation the GPU often sits idle, not for lack of work but because the CPU hasn't finished housekeeping for the next token. Moondream calls that gap a GPU bubble and rebuilt its Photon engine to hide it, overlapping the next forward pass with the sampling of the previous one.
The payoff scales with the machine. On an RTX 3090 the trick adds about 6.5%; on a B200, where CPU sync is a bigger slice of a tiny 2.4ms forward pass, it adds 35.4%. An inference engineer pushed back: the win looks this big only because the model is small.
Sign in to save
