Tag

llama.cpp

5 stories

Not just a headline — the discussion unpacked

The top HN threads: facts from the discussions, both sides, insider voices. Email, Telegram, or RSS.

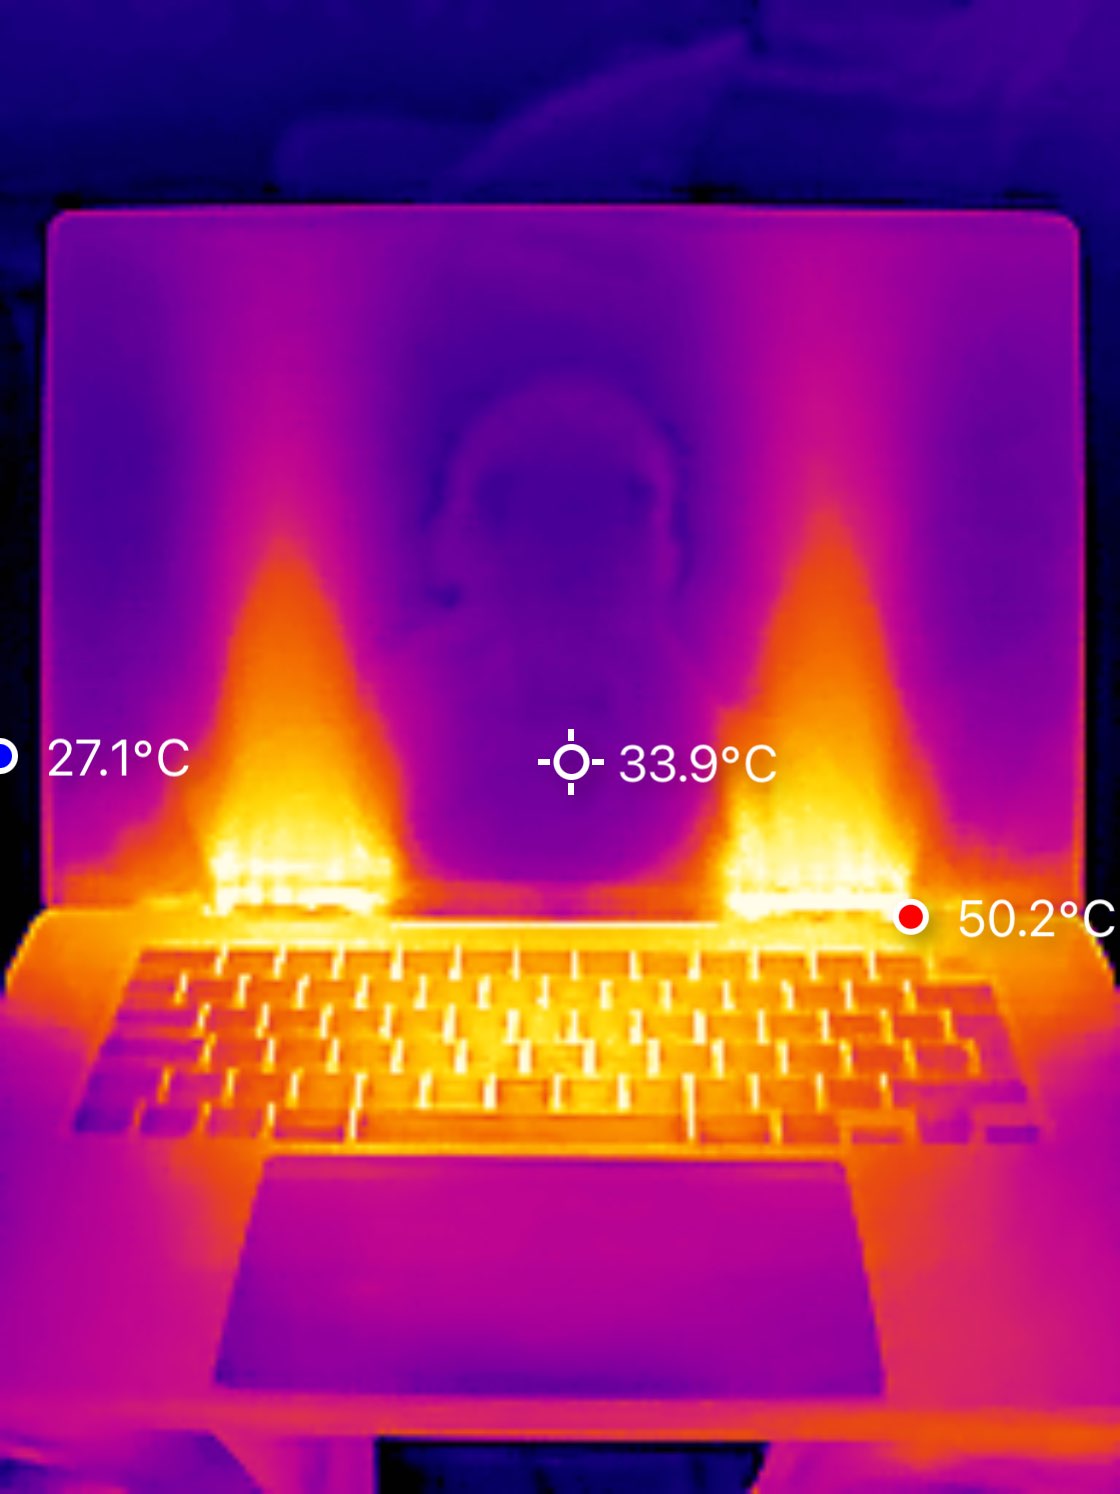
A 27B model runs local coding well — on a $6,699 laptop that burns your fingers (quesma.com)

The post pits the dense 27B against the faster 35B mixture-of-experts variant and argues for quality over throughput — 'I'd rather generate a third as much code, but of higher quality.' It ran the model through a hex-minesweeper build and a candle-shop landing page.

A founder who owns the exact machine pushed back hard: run a heavy job on the laptop itself and your fingers burn and the fans scream. His fix — stick a Mac Mini in the basement and reach it over Tailscale, at a third of the price.

🚀Tech ★ 649 · 💬 528 · Jun 30 · #AI#dev tools#hardware#Apple#DeepSeek#Gemma+2

80 tokens/sec on two mismatched GPUs — and a thread asking if self-hosting still makes sense (imil.net)

The trick is llama.cpp with speculative decoding and a tuned tensor split across two architectures Nvidia never meant to pair. The catch a reader measured: about 700W under load, enough to heat the room.

The thread turned into a referendum. One reader pays roughly $3 per million tokens in the cloud, unquantized, for the same model; another mourns that the run-your-own-hardware ethos is 'basically dead.'

He hit 72 tokens/sec coding locally on a MacBook. The thread asked: why not just use Ollama? (ikyle.me)

The guide wires up an offline coding agent on a 64GB M1 Max: llama.cpp built with Metal, Gemma 4 in Q4, and a Multi-Token Prediction draft model that lifts generation from 58 to 72 tokens/sec.

The thread's sharpest critique wasn't the setup but the metric: every local-AI post benchmarks tokens per second, none benchmark answer quality. 'Quickly serving me slop doesn't make it more useful.'