Tag

Fable

8 stories

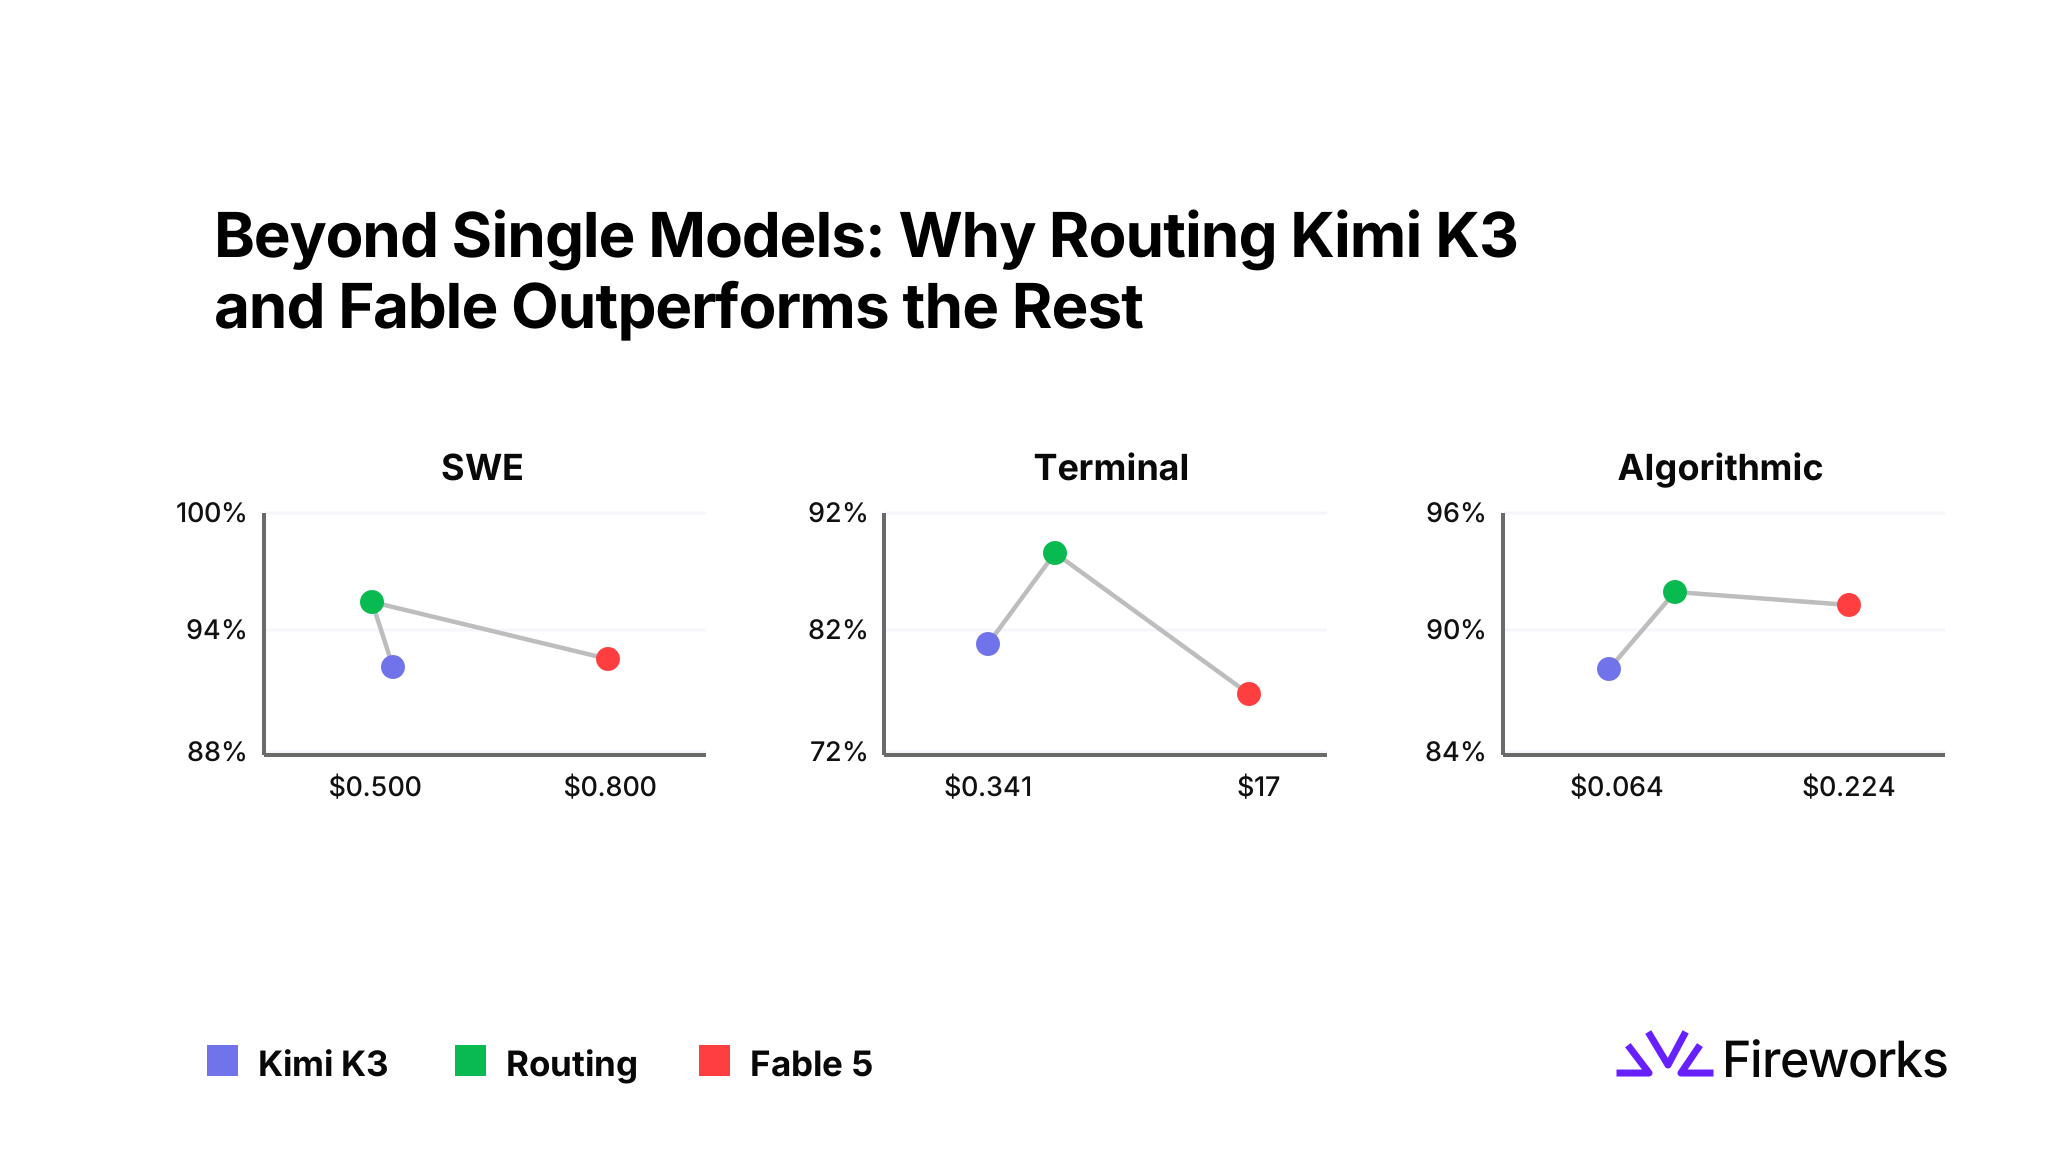
Fireworks Says Its Router Sent 96% of Tasks to Kimi K3, Not Fable (fireworks.ai)

That simulated router sent the bulk of 1,030 real coding, legal and terminal tasks to Kimi K3, up to 96% in one category, cutting Fireworks' own bill by as much as 50x versus running Fable alone on the same work.

A regular Fireworks customer in the thread went further, accusing the company of inflating its own throughput numbers by 50-100% elsewhere, and pointing out that the router this whole post is built around isn't a product anyone can actually buy yet.
Not just a headline — the discussion unpacked

The top HN threads: facts from the discussions, both sides, insider voices. Email, Telegram, or RSS.

An AI disproved a century-old math conjecture during the World Cup final (xenaproject.wordpress.com)

PhD students are now expected to pay $200 a month for access to models like Sol and Fable — Harvard already comps the subscription for every student, postdoc and faculty member in its math department.

Not everyone in the thread is impressed: one commenter dug into the Jacobian conjecture's citation history and found mathematicians had already bounded the search space by 1983 — the AI didn't discover new territory, it just finally searched it.

Command and Conquer Generals ported natively to iPhone, iPad and Apple Silicon (github.com)

Ammaar Reshi took EA's GPL v3 Generals source, built on the GeneralsX macOS/Linux port, and shipped native ARM64 iOS and iPadOS builds of Zero Hour with RTS touch controls.

The engine is unmodified; rendering runs DirectX 8 to DXVK to Vulkan to MoltenVK to Metal, five layers deep. No assets ship; you supply your own Steam copy.

The 'using Fable' credit drew fire: one game dev counted just 19 of 2000 commits from the model and called the headline clickbait.

Cursor's benchmark says its cheap model rivals the frontier. A rival benchmark says it scores 16 (cursor.com)

On Cursor's numbers, Composer 2.5 hits 63.2% accuracy at $0.55 a task — the cheapest in the field, and framed as near-frontier. The presentation even flipped the cost axis so cheapest sits on the right, which several readers found conveniently confusing.

The rebuttal came with citations. On the DeepSWE benchmark — 'probably the hardest to game' — GPT-5.5 gets 64, Opus 4.8 gets 56, and Composer 2.5 gets 16. A developer who's used both models heavily called the parity claim 'absolutely farcical': faster, yes; anywhere near as good, no.

Anthropic locked away Mythos as too dangerous. A hobbyist benchmark says: maybe (swelljoe.com)

Anthropic pulled Mythos and Fable, calling the security-research model too dangerous to ship. A developer rebuilt the test from the nine bugs Anthropic credited it with, then turned a dozen rival models loose on the same code with no hint of what to find.

The headline isn't the frontier. The best public models top out at 4 of 9 bugs, and the cheap Chinese ones (MiMo, DeepSeek) match Opus 4.8 at a tenth the price. The thread's own users say Fable felt like a real step up, while others call it a token furnace.

Anthropic's new terms can ask for your ID or your facial geometry (anthropic.com)

Anthropic's policy (published June 8, effective July 8) says it may ask users to verify age or identity, collecting a government ID image, a face photo or video, and facial-geometry templates that may count as 'biometric data.' Reaction ran to passports, Peter Thiel, and fleeing to open-weight models.

A high-karma commenter cut through it with receipts: ID verification quietly rolled out months ago. Another named the real bind - governments demanding both child-safety age-gates and accountability after an AI-encouraged shooting.

🌍Other ★ 187 · 💬 169 · Jun 24 · #AI#policy#privacy#Anthropic#Claude#Fable+1

From Haiku to 'Overwhelmingly Large Narrative Unit': extrapolating Anthropic's model names (samwilkinson.io)

The invented roster runs to 'Cinematic Universe (Director's Cut): same answer, 42% more tokens' and 'Diatribe: Sonnet, but angry.'

A commenter decoded the literary theme as a Lovecraft reference — and hoped future models 'will be kind enough not to behave like malevolent gods.'

🚀Tech ★ 287 · 💬 80 · Jun 11 · #AI#culture#Anthropic#Claude#Fable+1

Anthropic's security model blocks the researchers it was built to help (techcrunch.com)

Fable, the public version of Anthropic's Mythos security model, pauses and refuses anything in the 'lexical field' of cybersecurity. Hit a guardrail and it falls back to Claude Opus 4.8 — a weaker model for the task.

The complaint that stuck wasn't about safety theatre. It was the billing question: if it silently swaps in a cheaper model mid-request, who pays the original rate?