Tag

Z.ai

7 stories

GLM-5.3 arrives with coding claims and a safety argument (z.ai)

GLM-5.3 is presented as a frontier coding model with emergent cyber capabilities. HN readers liked the reported numbers but were cautious about turning release benchmarks into deployment decisions.

The sharper disagreement concerned access: if attackers can use capable models, defenders may need comparable tools without an approval process that only large labs can navigate.

🚀Tech ★ 1.0K · 💬 517 · Aug 15 · #AI#dev tools#security#DeepSWE#GLM-5.3#Z.ai

Not just a headline — the discussion unpacked

The top HN threads: facts from the discussions, both sides, insider voices. Email, Telegram, or RSS.

An open model at $4.40/MTok threatens frontier labs' 90% inference margins (martinalderson.com)

GLM 5.2 lists near $4.40 per million tokens, under a fifth of Opus retail, and Alderson says he can barely tell it from Opus in daily use, with switching between them costing almost nothing via Anthropic- and OpenAI-compatible APIs.

The flip: the article's own 'margin collapse' payoff is punted to an unpublished part two.

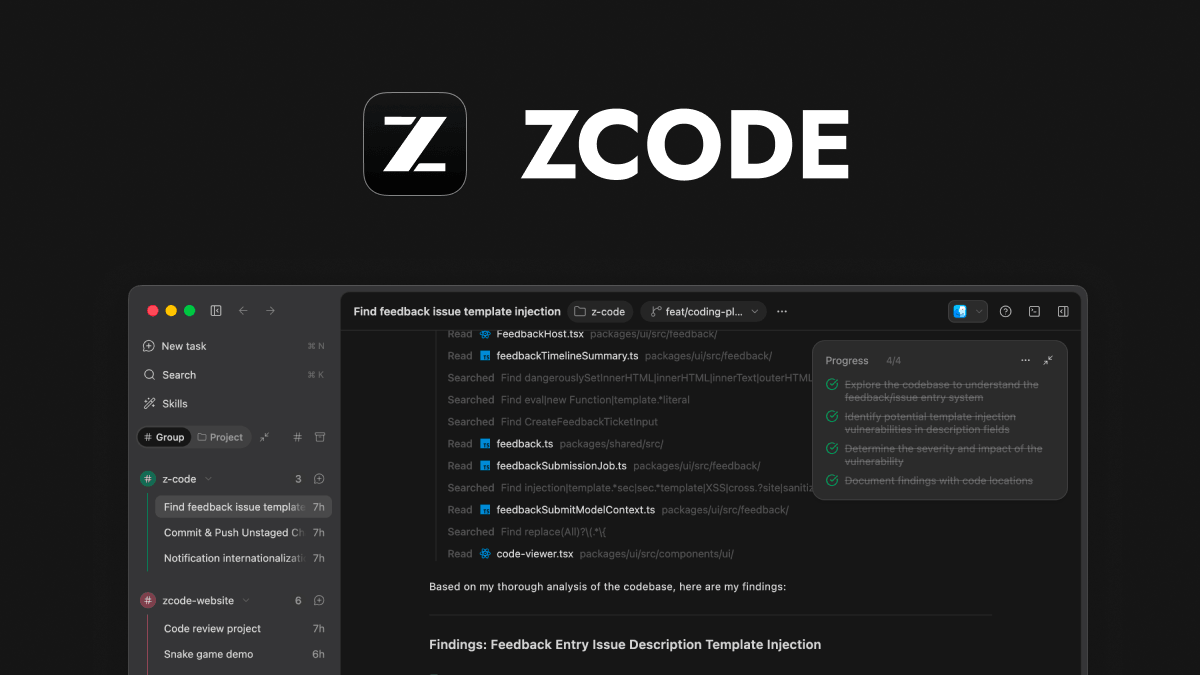
Z.ai's ZCode chases Claude Code with GLM-5.2, and looks a lot like Codex (zcode.z.ai)

Plans run from $16.20 to $144 a month, and GLM Coding subscribers get a quota discount inside ZCode: peak hours (14:00-18:00) drop from 3x to 2x and off-peak from 1x to 0.67x, roughly a 1.5x effective allowance. The base allowance itself is never stated in tokens.

Developers ask why a lab that open-weights its models keeps the harness closed, and a Chinese-owned agent with full system permissions drew explicit trust warnings.

A $5 model coded a WebGL game in 70 minutes; Opus needed 33 (techstackups.com)

GLM-5.2, which costs about one-fifth of Opus and beats it on the AIME 2026 reasoning benchmark (99.2 vs 95.7), took 1h10m and produced a buggy game; Opus finished in 33m30s. The split: GLM-5.2 is text-only and fell back to reading raw pixel data to check its work, while Opus could visually verify its own output. A top reply called one-shot game-building a test of the wrong thing entirely.

GLM-5.2 tops open-weights at 51 on the Intelligence Index — and burns 43k tokens to get there (artificialanalysis.ai)

Z.ai's GLM-5.2 (744B total, 40B active) is now the top open-weights model on Artificial Analysis at 51, ahead of DeepSeek V4 Pro and Kimi K2.6, and it scored 1524 on one benchmark versus GPT-5.5's 1514.

The catch is verbosity: 43k tokens per task, 37k of it reasoning. One tester clocked 15 minutes and 45k tokens before the first file appeared. Sibylline's chief scientist still recommends it — pair GLM for writing with a cheap GPT sub for review, and you've got near-Opus output at a fraction of the price.

China's GLM 5.2 shipped open-weight the same hour Washington froze Fable, benchmarks not even ready (twitter.com)

The founder's launch note reads like a manifesto: 'Frontier Intelligence Belongs to Everyone… The path to AGI must never be enclosed by high walls.' The timing was precise, posted as Anthropic got the government letter.

Three Chinese labs shipped open models in days while a U.S. model went dark, a contrast one builder called fiction. A day-one user pegged GLM 5.2 between Sonnet and Opus, with Z.ai's usual caveat: reliability.